

The frontier AI race has spent the last few years operating on a pretty simple assumption: build the smartest model, win the leaderboard, collect your crown.
Grok 4.7 makes that math a little messier.
xAI, now operating under SpaceXAI, released Grok 4.7 on September 21 as its strongest model yet for coding and knowledge work. It uses a larger base model than Grok 4.6, underwent a longer reinforcement-learning run focused on multi-hour tasks, and was trained to verify its work more carefully over long jobs.
But the interesting part isn’t that Grok suddenly became unquestionably smarter than GPT-6 Astra or Claude Fable 5.1.
It didn’t.
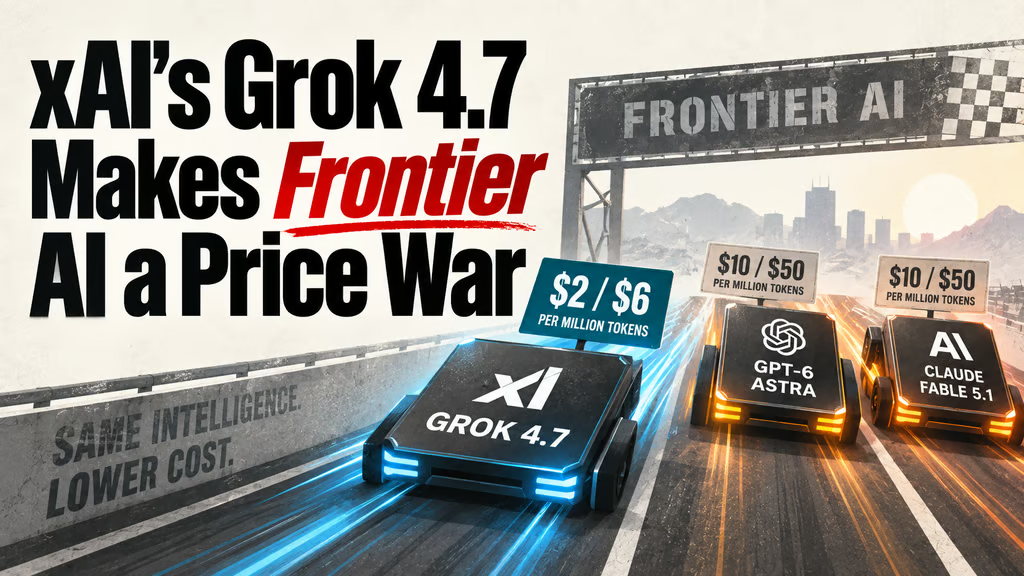
The interesting part is that xAI is getting close enough in important categories while charging $2 per million input tokens and $6 per million output tokens.
For comparison, both GPT-6 Astra and Fable 5.1 list standard API pricing of $10 per million input tokens and $50 per million output tokens.
So the new question at the frontier is becoming less “Who built the smartest model?” and more:
How much extra are you willing to pay for the last chunk of capability?
Grok 4.7 got considerably better
This isn’t just Grok 4.6 with a shiny new number.
According to xAI’s Grok 4.7 announcement, the company moved to a larger base model and extended reinforcement training toward harder problems designed to take hours rather than minutes.
That shows up in xAI’s evaluations.
On CursorBench 4.0, which tests longer-running software engineering work, Grok 4.7 scored 46.3%, up from Grok 4.6’s 40.4%. It reached 71% on DeepSWE v1.1 at high effort and jumped from 20.3% to 38% on xAI’s Terminal-Bench 4.0 setup.
Some of its more specialized scores are even stranger — in a good way.
Grok 4.7 hit 64% on an electrical-engineering benchmark and 19.6% on Harvey’s legal-agent benchmark. In xAI’s reported GDPval results, which are meant to approximate professional knowledge work, Grok landed between Fable 5.1 and GPT-6 Astra.
So this isn’t a case where xAI built a bargain-bin model and slapped “frontier” on the box.
Grok can genuinely compete with much more expensive models on some useful tasks.
Just not all of them.
Astra and Fable are still out front
The independent numbers make Grok’s position a little clearer.
Artificial Analysis currently gives Grok 4.7 a score of 46 on its broader Intelligence Index. GPT-6 and Claude Fable 5.1 both score 53.
The gap gets more obvious on some long-horizon agentic tasks. The Decoder cites Artificial Analysis results putting Grok 4.7 at 26% on Terminal-Bench 4.0, compared with roughly 60% for GPT-6 Astra and 55% for Fable 5.1.
Yes, that Terminal-Bench number differs from xAI’s own 38% result.
Welcome to benchmarking AI agents in 2026.
Different harnesses, reasoning settings, tool configurations, token budgets, and evaluation environments can move these scores around considerably. We saw the same problem after GPT-6 Astra launched, when the exact same underlying model could look dramatically different depending on the system wrapped around it.
That makes broad declarations that Model X has “beaten” Model Y increasingly useless.
The more useful conclusion is narrower: Astra and Fable still appear stronger overall, especially for difficult long-running agentic work. Grok 4.7 has nevertheless moved close enough to compete seriously on a growing number of tasks.
And then the price tag enters the room.
xAI is attacking the frontier from underneath
At list price, one million input tokens plus one million output tokens costs $8 with standard Grok 4.7.
That same hypothetical token mix costs $60 with standard GPT-6 Astra or Fable 5.1.
Real workloads are more complicated. Anthropic, for example, cut Fable 5.1’s cache-read pricing to $0.25 per million tokens and says caching can reduce typical workload costs by roughly 25% and highly agentic workloads by as much as 45%. OpenAI also offers cached-input pricing.
Still, the gap is enormous.
That matters because long-running agents consume a lot of tokens.
The economics feel different when your AI answers six questions versus when it spends three hours reading a repository, testing software, reopening files, using tools, recovering from errors, and checking its own work.
Suddenly, token prices stop looking like tiny decimals on an API page.
They start looking like infrastructure costs.
And xAI isn’t the only company squeezing from below.
Google’s Gemini 3.8 Flash, released earlier this month, targets long-horizon software engineering and autonomous agents at an introductory $0.75 per million input tokens and $3.75 per million output tokens through the end of 2026.
DeepSeek also just released V4.1 Flash, using a new architecture designed specifically to reduce inference and cache costs while remaining competitive on agentic benchmarks.
So the model market is developing two frontiers at once:
There’s the capability frontier, where OpenAI and Anthropic are currently fighting over the hardest tasks.
And there’s a rapidly advancing economic frontier, where companies are trying to deliver enough of that intelligence at dramatically lower cost.
Grok 4.7 is xAI’s strongest entry into the second fight yet.
Being No. 1 may matter less than being close
This changes the power dynamic between AI labs.
For OpenAI and Anthropic, raw intelligence remains an enormous advantage. GPT-6 Astra pushes particularly hard into computer use, coding, science, and extremely long autonomous work. Anthropic’s Fable 5.1 release similarly centers coding and long-running knowledge work while cutting the cost of repeated context.
But their competitors don’t necessarily have to beat those models everywhere.
They have to get close enough that customers start asking whether the premium is worth it.
Imagine an AI agent completing thousands of internal coding, research, document-processing, or support jobs every day.
If Fable solves 90 jobs correctly and Grok solves 86, that gap might be extremely important.
Or it might not matter at all if Grok makes the workflow dramatically cheaper.
The answer depends on the work.
For a cybersecurity investigation, critical financial analysis, or a software task where one mistake creates a week of cleanup, paying for the strongest available model can make perfect sense.
For high-volume document processing, internal research, first-pass coding, routine agent work, or jobs with strong automated verification, economics may dominate.
That gives companies like xAI, Google, and DeepSeek another path into the frontier conversation.
They don’t necessarily need to knock OpenAI and Anthropic off the top.
They can make the top expensive.
The frontier is becoming a curve, not a leaderboard
This may be the more important shift behind Grok 4.7.
A year ago, comparing AI models often meant opening a leaderboard and looking at which bar went highest.
That’s increasingly the wrong abstraction.
Models now differ across coding, computer use, research, professional judgment, latency, context handling, multimodality, safety restrictions, ecosystem integrations, and critically: cost.
GPT-6 Astra can handle workloads Grok 4.7 may still struggle to complete.
Fable 5.1 can outperform Grok on important coding benchmarks.
Grok can beat both on specific professional benchmarks.
Gemini 3.8 Flash can undercut Grok on token pricing.
DeepSeek continues pushing strong agentic capabilities into cheaper architectures.
And another release could scramble that entire list before we go to bed tonight, because that's.how.ai.rolls.
The competitive frontier is becoming a curve of capability versus cost, rather than a single point occupied by whichever company released the biggest model last.
That makes the power balance much less comfortable for whoever happens to be No. 1.
OpenAI and Anthropic can keep pushing the ceiling upward. But every time xAI, Google, DeepSeek, or another lab gets closer for a fraction of the cost, yesterday’s premium intelligence becomes tomorrow’s commodity infrastructure.
Grok 4.7 hasn’t taken the crown.
It might be doing something more annoying for the companies wearing it:
making the crown cheaper.
